Transformers KV Caching Explained
In this reference
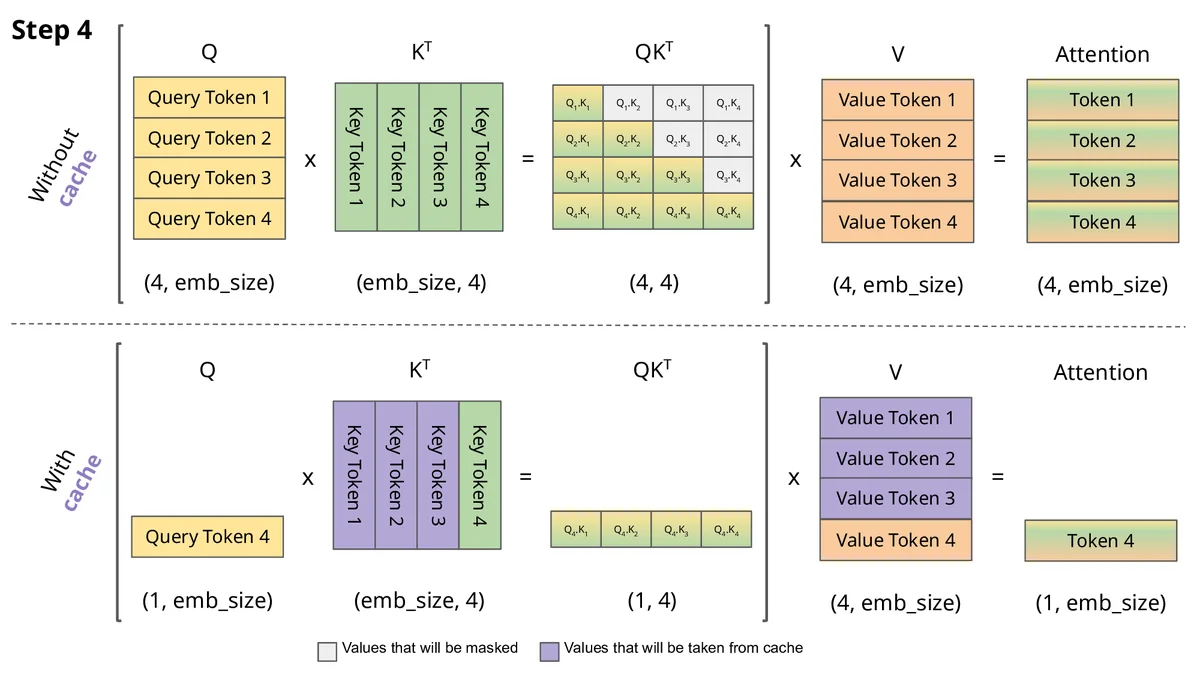
An illustrated explanation of reusing attention states to speed up autoregressive generation.
Cite the original work
João Lages (8 October 2023). Transformers KV Caching Explained. Medium. https://medium.com/@joaolages/kv-caching-explained-276520203249
View BibTeX
@misc{transformers_kv_caching_explained,
  author = {João Lages},
  title = {{Transformers KV Caching Explained}},
  howpublished = {Medium},
  url = {https://medium.com/@joaolages/kv-caching-explained-276520203249},
  year = {2023}
}