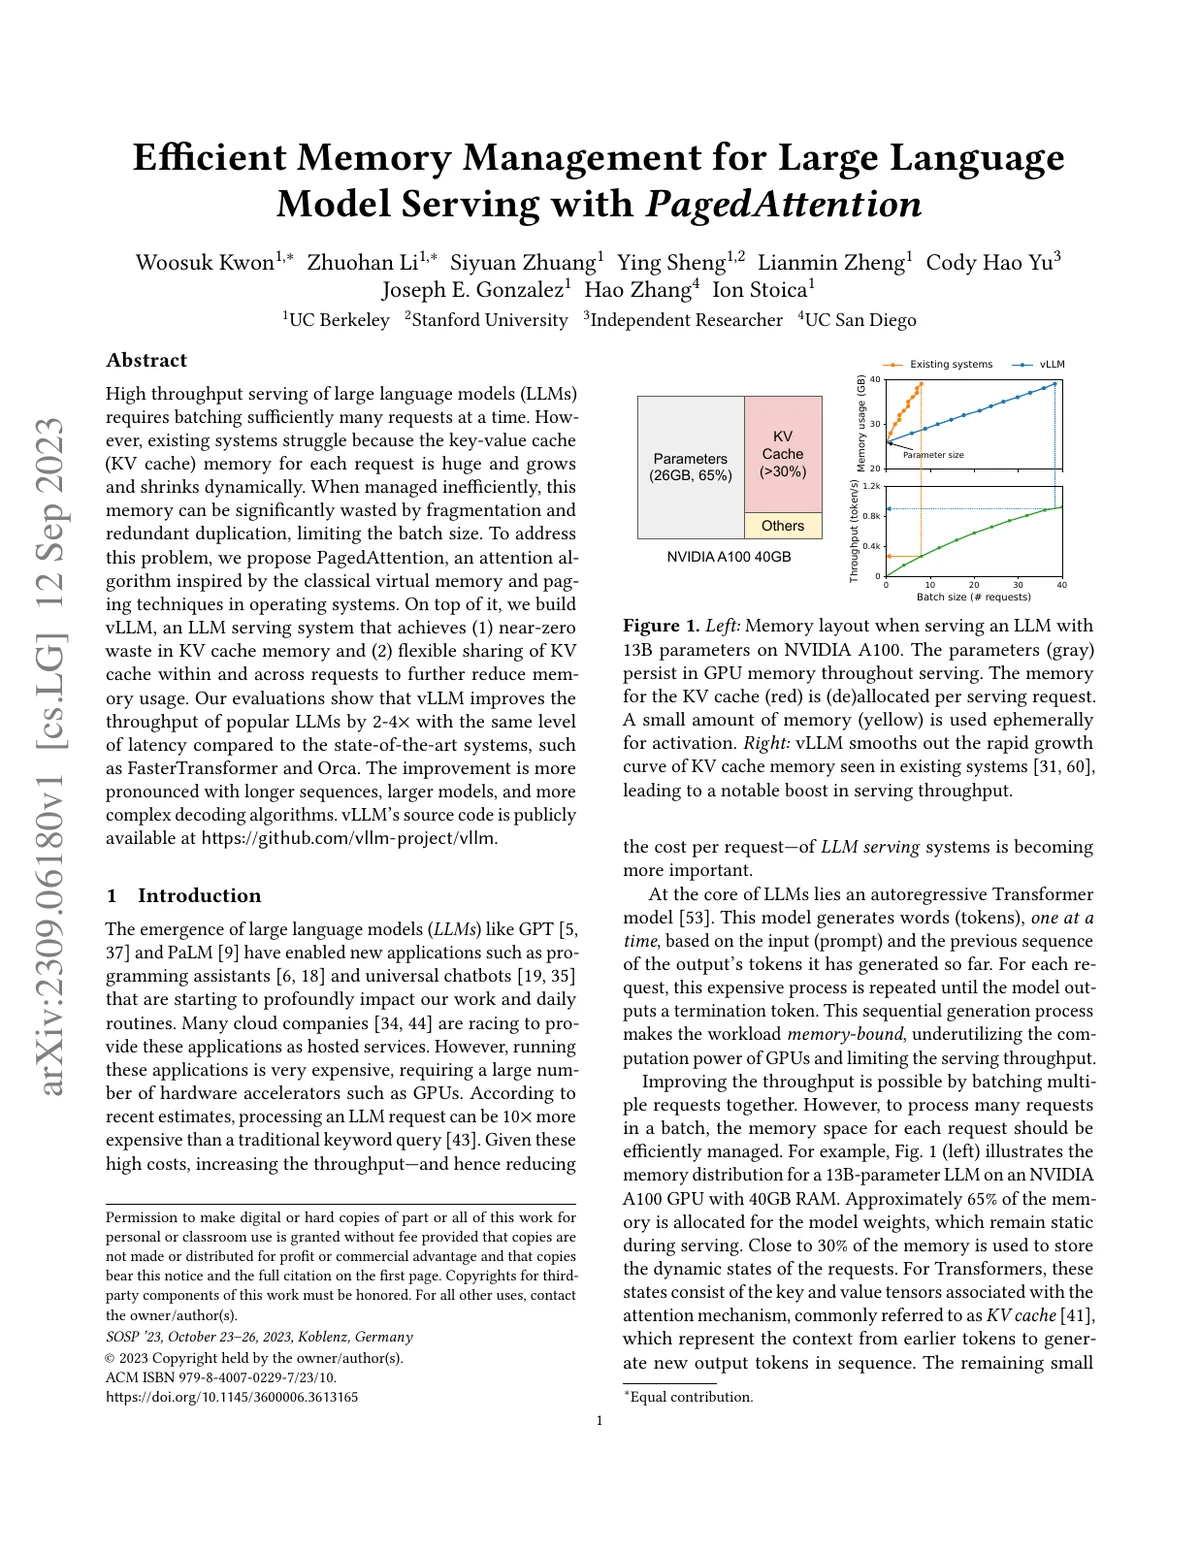
Efficient Memory Management for Large Language Model Serving with PagedAttention
In this reference
The vLLM paper introduces PagedAttention, using ideas from virtual memory to manage the key-value cache and improve LLM serving throughput.
Cite the original work
Woosuk Kwon & Zhuohan Li & Siyuan Zhuang & Ying Sheng & Lianmin Zheng & Cody Hao Yu & Joseph E. Gonzalez & Hao Zhang & Ion Stoica (12 September 2023). Efficient Memory Management for Large Language Model Serving with PagedAttention [Research paper]. arXiv. https://arxiv.org/abs/2309.06180v1
View BibTeX
@misc{pagedattention,
  author = {Woosuk Kwon and Zhuohan Li and Siyuan Zhuang and Ying Sheng and Lianmin Zheng and Cody Hao Yu and Joseph E. Gonzalez and Hao Zhang and Ion Stoica},
  title = {{Efficient Memory Management for Large Language Model Serving with PagedAttention}},
  howpublished = {arXiv},
  url = {https://arxiv.org/abs/2309.06180v1},
  year = {2023},
  version = {arXiv v1}
}