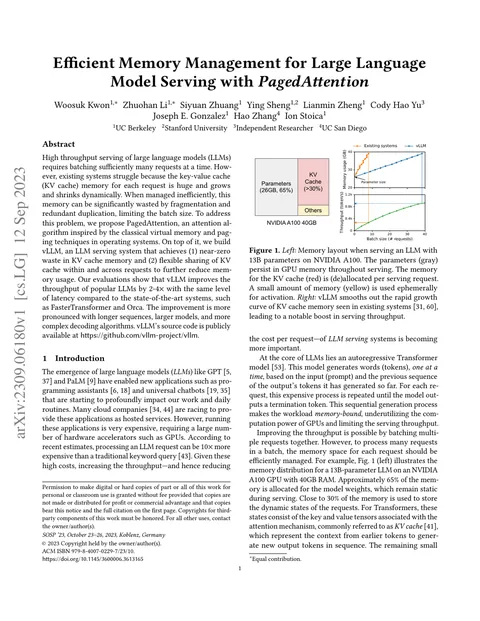
vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention
The original vLLM announcement and its approach to memory-efficient model serving.
vllm.ai20 June 2023Public source
Read the article
In this reference
The original vLLM announcement and its approach to memory-efficient model serving.
Cite the original work
vLLM Team (20 June 2023). vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention. vllm.ai. https://vllm.ai/blog/2023-06-20-vllm
View BibTeX
@misc{vllm_easy_fast_and_cheap_llm_serving_with_pagedattention,
  author = {{vLLM Team}},
  title = {{vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention}},
  howpublished = {vllm.ai},
  url = {https://vllm.ai/blog/2023-06-20-vllm},
  year = {2023}
}