All About Transformer Inference
Why I kept it
A reference on how transformers are served.
François Paupier
Google DeepMind4 February 2025Public source
Read the article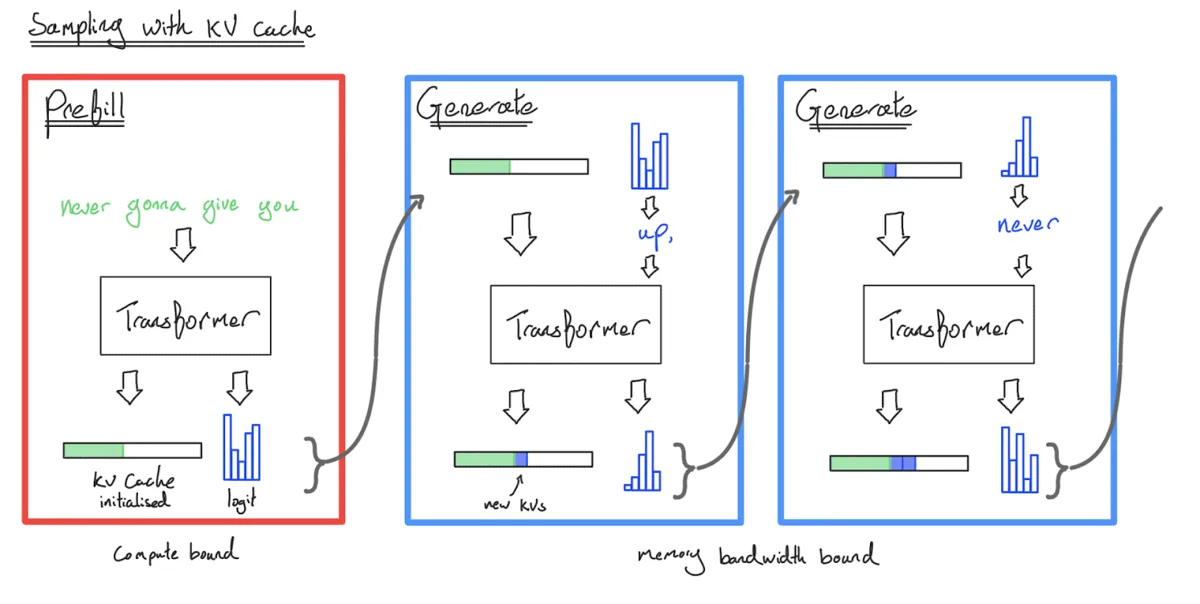
In this reference
Part 7 of How to Scale Your Model: Transformer inference, from sampling one token to running a model across accelerators.
From the chapter
Performing inference on a Transformer can be very different from training. Partly this is because inference adds a new factor to consider: latency.
Jacob Austin, Sholto Douglas, Roy Frostig, Anselm Levskaya, Charlie Chen, Sharad Vikram, Federico Lebron, Peter Choy, Vinay Ramasesh, Albert Webson, and Reiner Pope
Cite the original work
Jacob Austin & Sholto Douglas & Roy Frostig & Anselm Levskaya & Charlie Chen & Sharad Vikram & Federico Lebron & Peter Choy & Vinay Ramasesh & Albert Webson & Reiner Pope (4 February 2025). All About Transformer Inference. Google DeepMind. https://jax-ml.github.io/scaling-book/inference/
View BibTeX
@misc{all_about_transformer_inference,
  author = {Jacob Austin and Sholto Douglas and Roy Frostig and Anselm Levskaya and Charlie Chen and Sharad Vikram and Federico Lebron and Peter Choy and Vinay Ramasesh and Albert Webson and Reiner Pope},
  title = {{All About Transformer Inference}},
  howpublished = {Google DeepMind},
  url = {https://jax-ml.github.io/scaling-book/inference/},
  year = {2025}
}