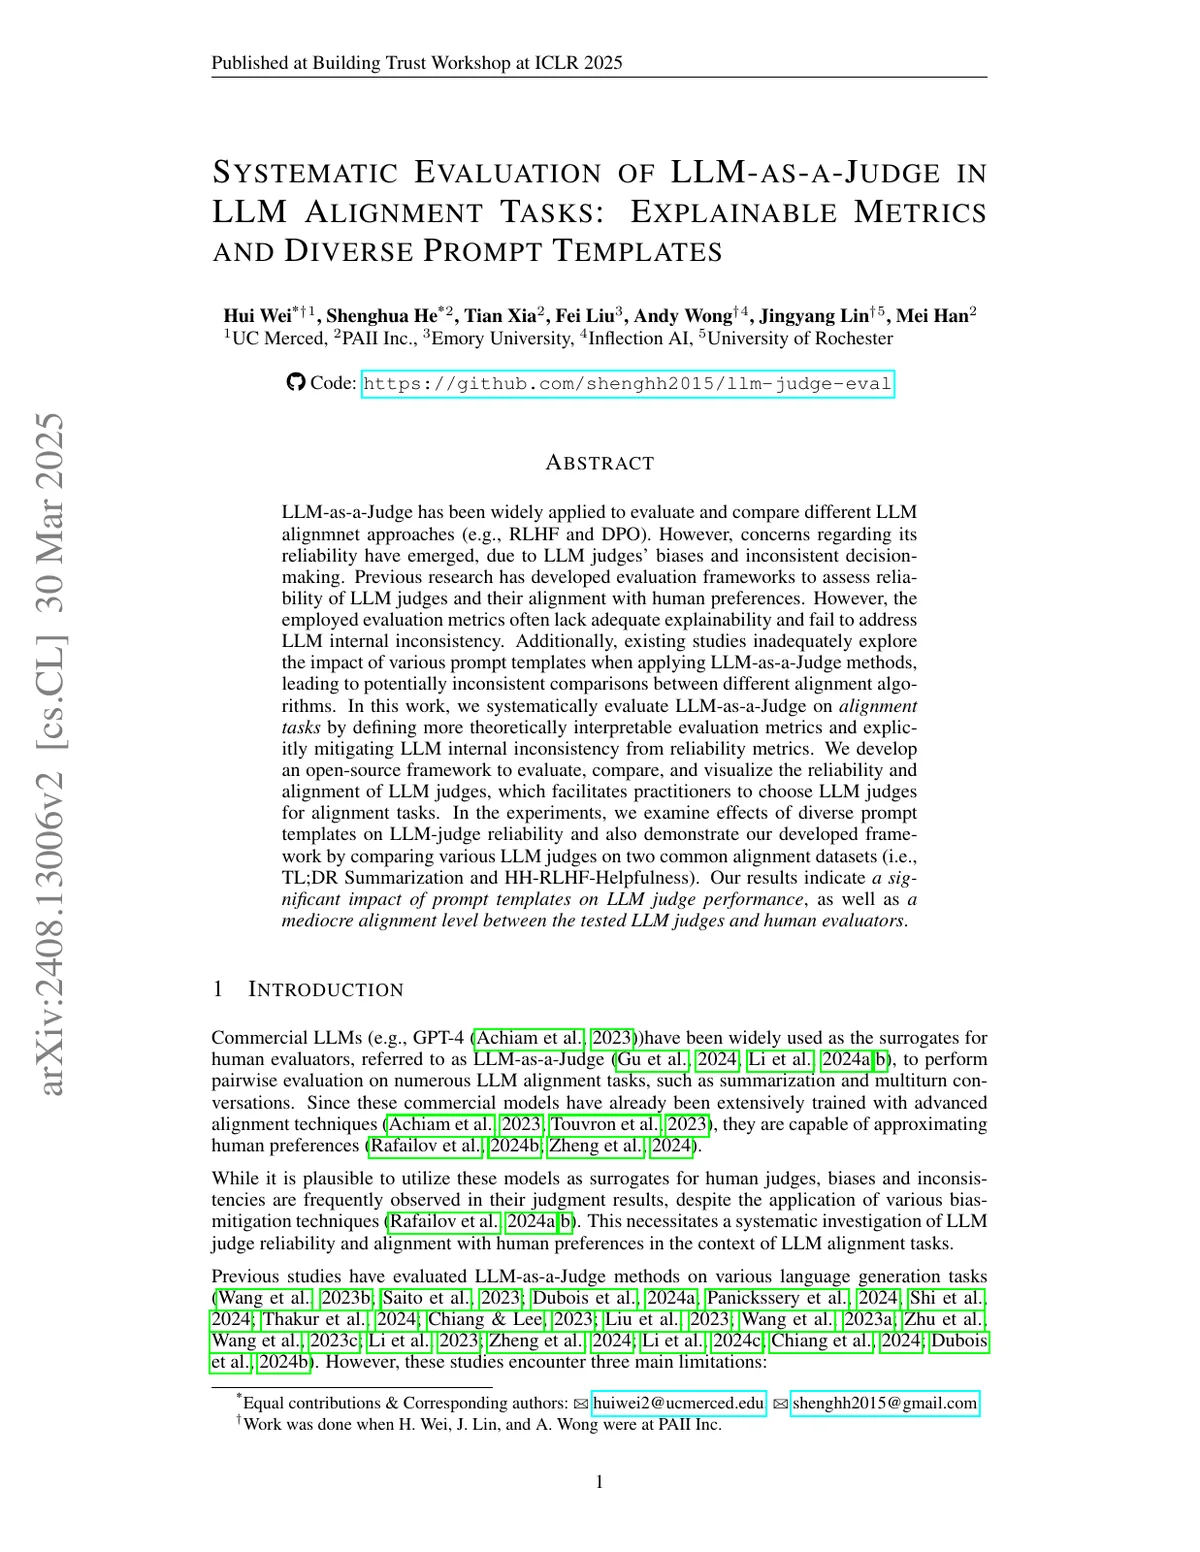
Systematic Evaluation of LLM-as-a-Judge in LLM Alignment Tasks: Explainable Metrics and Diverse Prompt Templates
In this reference
A systematic study of language models used as judges in alignment evaluation.
Cite the original work
Hui Wei & Shenghua He & Tian Xia & Fei Liu & Andy Wong & Jingyang Lin & Mei Han (23 August 2024). Systematic Evaluation of LLM-as-a-Judge in LLM Alignment Tasks: Explainable Metrics and Diverse Prompt Templates [Research paper]. arXiv. https://arxiv.org/abs/2408.13006v2
View BibTeX
@misc{systematic_evaluation_of_llm_as_a_judge_in_llm_alignment_tasks_explainable_metrics_an,
  author = {Hui Wei and Shenghua He and Tian Xia and Fei Liu and Andy Wong and Jingyang Lin and Mei Han},
  title = {{Systematic Evaluation of LLM-as-a-Judge in LLM Alignment Tasks: Explainable Metrics and Diverse Prompt Templates}},
  howpublished = {arXiv},
  url = {https://arxiv.org/abs/2408.13006v2},
  year = {2024}
}