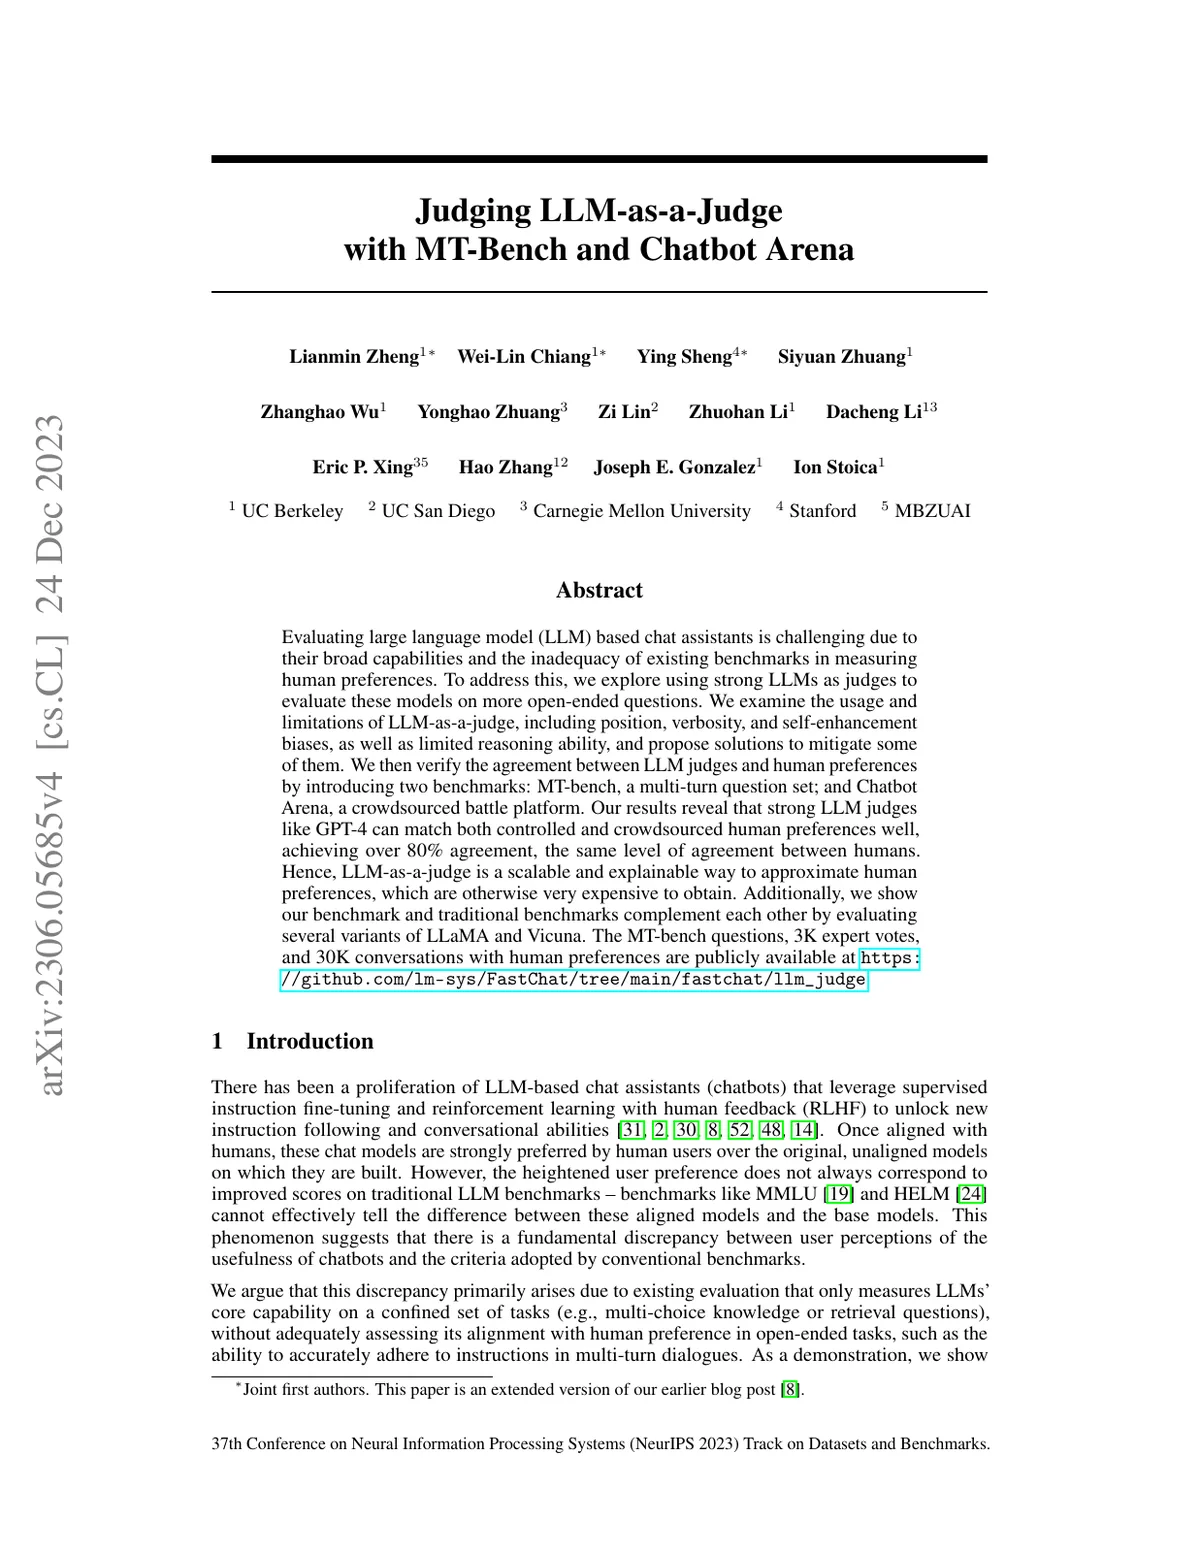
Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena
In this reference
An evaluation of LLM judges through MT-Bench and Chatbot Arena, studying agreement with human preferences alongside position, verbosity and other biases.
Cite the original work
Lianmin Zheng & Wei-Lin Chiang & Ying Sheng & Siyuan Zhuang & Zhanghao Wu & Yonghao Zhuang & Zi Lin & Zhuohan Li & Dacheng Li & Eric P. Xing & Hao Zhang & Joseph E. Gonzalez & Ion Stoica (9 June 2023). Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena [Research paper]. arXiv. https://arxiv.org/abs/2306.05685v4
View BibTeX
@misc{llm_as_judge,
  author = {Lianmin Zheng and Wei-Lin Chiang and Ying Sheng and Siyuan Zhuang and Zhanghao Wu and Yonghao Zhuang and Zi Lin and Zhuohan Li and Dacheng Li and Eric P. Xing and Hao Zhang and Joseph E. Gonzalez and Ion Stoica},
  title = {{Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena}},
  howpublished = {arXiv},
  url = {https://arxiv.org/abs/2306.05685v4},
  year = {2023},
  version = {arXiv v4}
}