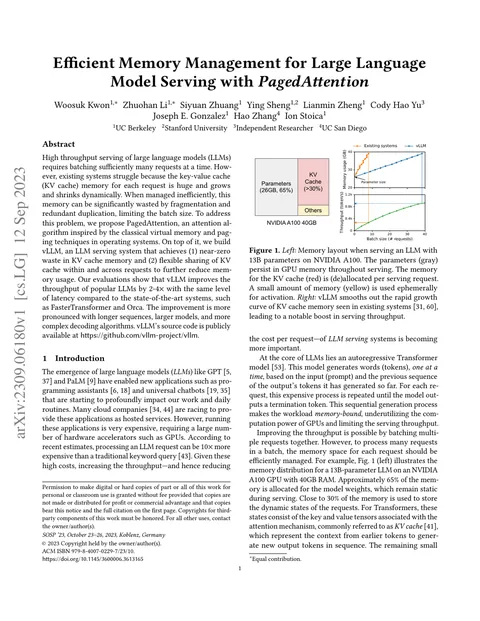
LLM Inference Performance Engineering: Best Practices
Measure and improve the latency, throughput and cost of serving LLMs.
Databricks12 October 2023Public source
Read the article
In this reference
An engineering guide to LLM inference latency, throughput and cost, covering GPU utilization, batching, memory and the difference between prefill and decoding.
Cite the original work
Megha Agarwal & Asfandyar Qureshi & Nikhil Sardana & Linden Li & Julian Quevedo & Daya Khudia (12 October 2023). LLM Inference Performance Engineering: Best Practices. Databricks. https://www.databricks.com/blog/llm-inference-performance-engineering-best-practices
View BibTeX
@misc{llm_inference_performance,
  author = {Megha Agarwal and Asfandyar Qureshi and Nikhil Sardana and Linden Li and Julian Quevedo and Daya Khudia},
  title = {{LLM Inference Performance Engineering: Best Practices}},
  howpublished = {Databricks},
  url = {https://www.databricks.com/blog/llm-inference-performance-engineering-best-practices},
  year = {2023}
}