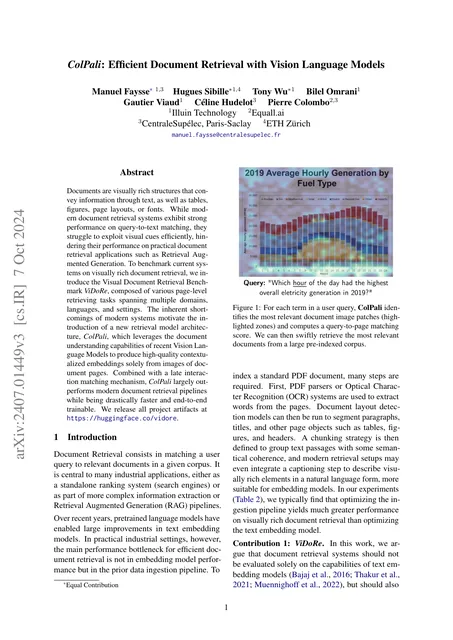
SmolVLM: Redefining small and efficient multimodal models
Smaller vision-language models for phones and edge devices.
arXiv7 April 2025Public source
Read the paper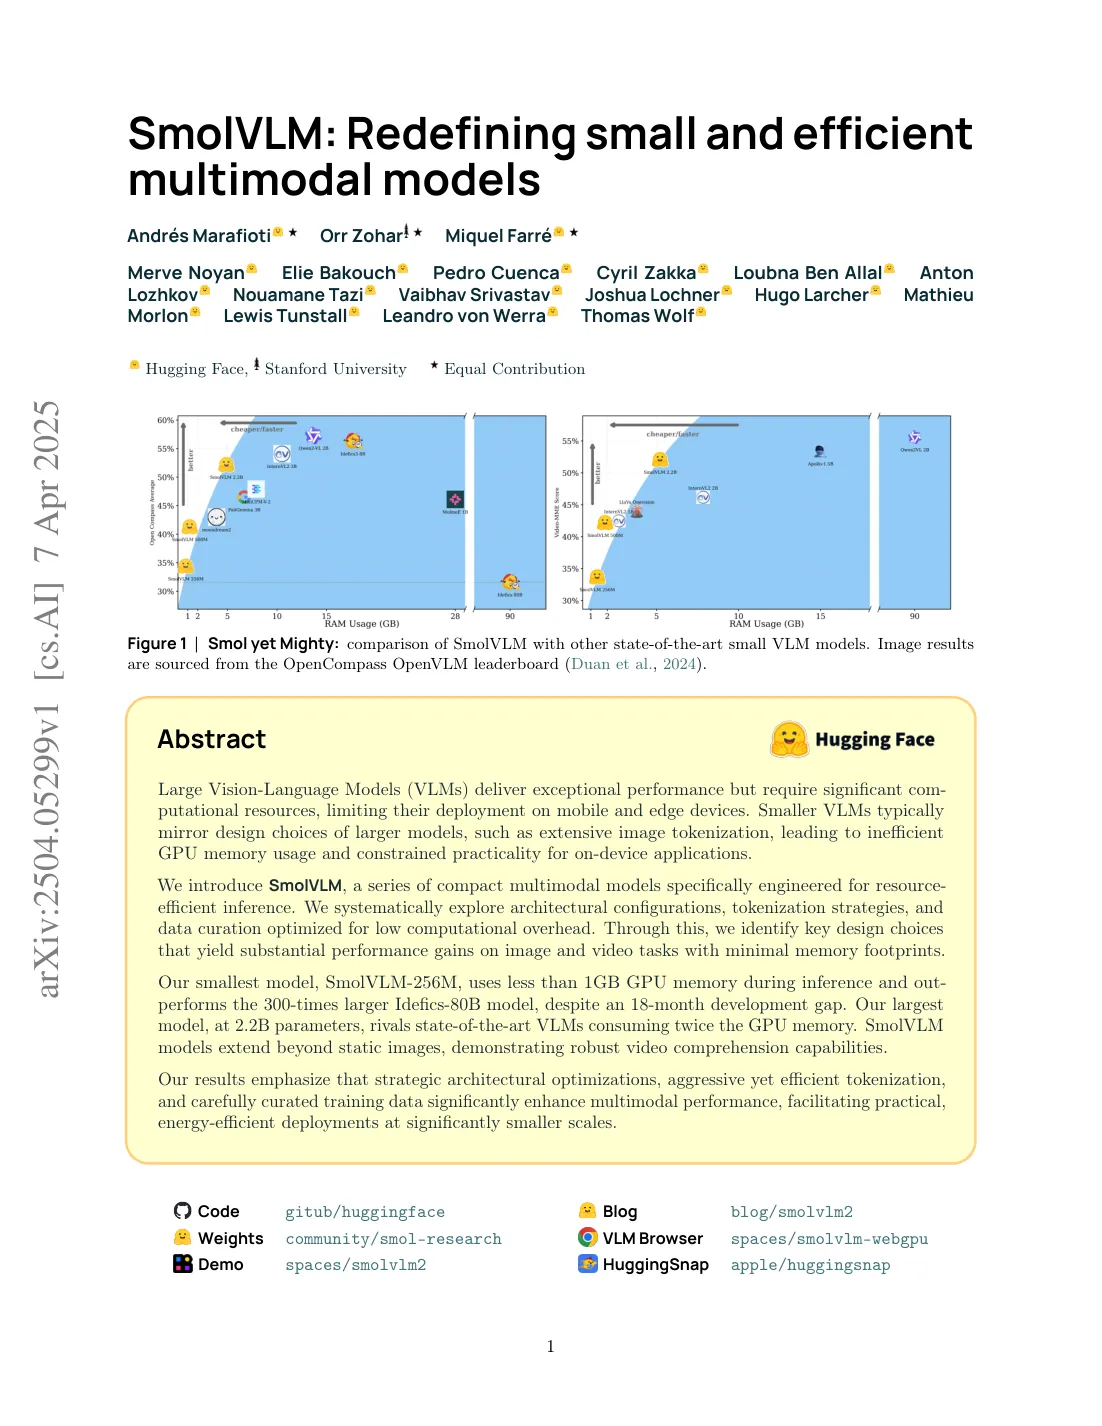
In this reference
A family of smaller vision-language models aimed at mobile and edge devices, instead of copying the image tokenization of the largest models.
Cite the original work
Andrés Marafioti & Orr Zohar & Miquel Farré & Merve Noyan & Elie Bakouch & Pedro Cuenca & Cyril Zakka & Loubna Ben Allal & Anton Lozhkov & Nouamane Tazi & Vaibhav Srivastav & Joshua Lochner & Hugo Larcher & Mathieu Morlon & Lewis Tunstall & Leandro von Werra & Thomas Wolf (7 April 2025). SmolVLM: Redefining small and efficient multimodal models [Research paper]. arXiv. https://arxiv.org/abs/2504.05299v1
View BibTeX
@misc{smolvlm,
  author = {Andrés Marafioti and Orr Zohar and Miquel Farré and Merve Noyan and Elie Bakouch and Pedro Cuenca and Cyril Zakka and Loubna Ben Allal and Anton Lozhkov and Nouamane Tazi and Vaibhav Srivastav and Joshua Lochner and Hugo Larcher and Mathieu Morlon and Lewis Tunstall and Leandro von Werra and Thomas Wolf},
  title = {{SmolVLM: Redefining small and efficient multimodal models}},
  howpublished = {arXiv},
  url = {https://arxiv.org/abs/2504.05299v1},
  year = {2025}
}