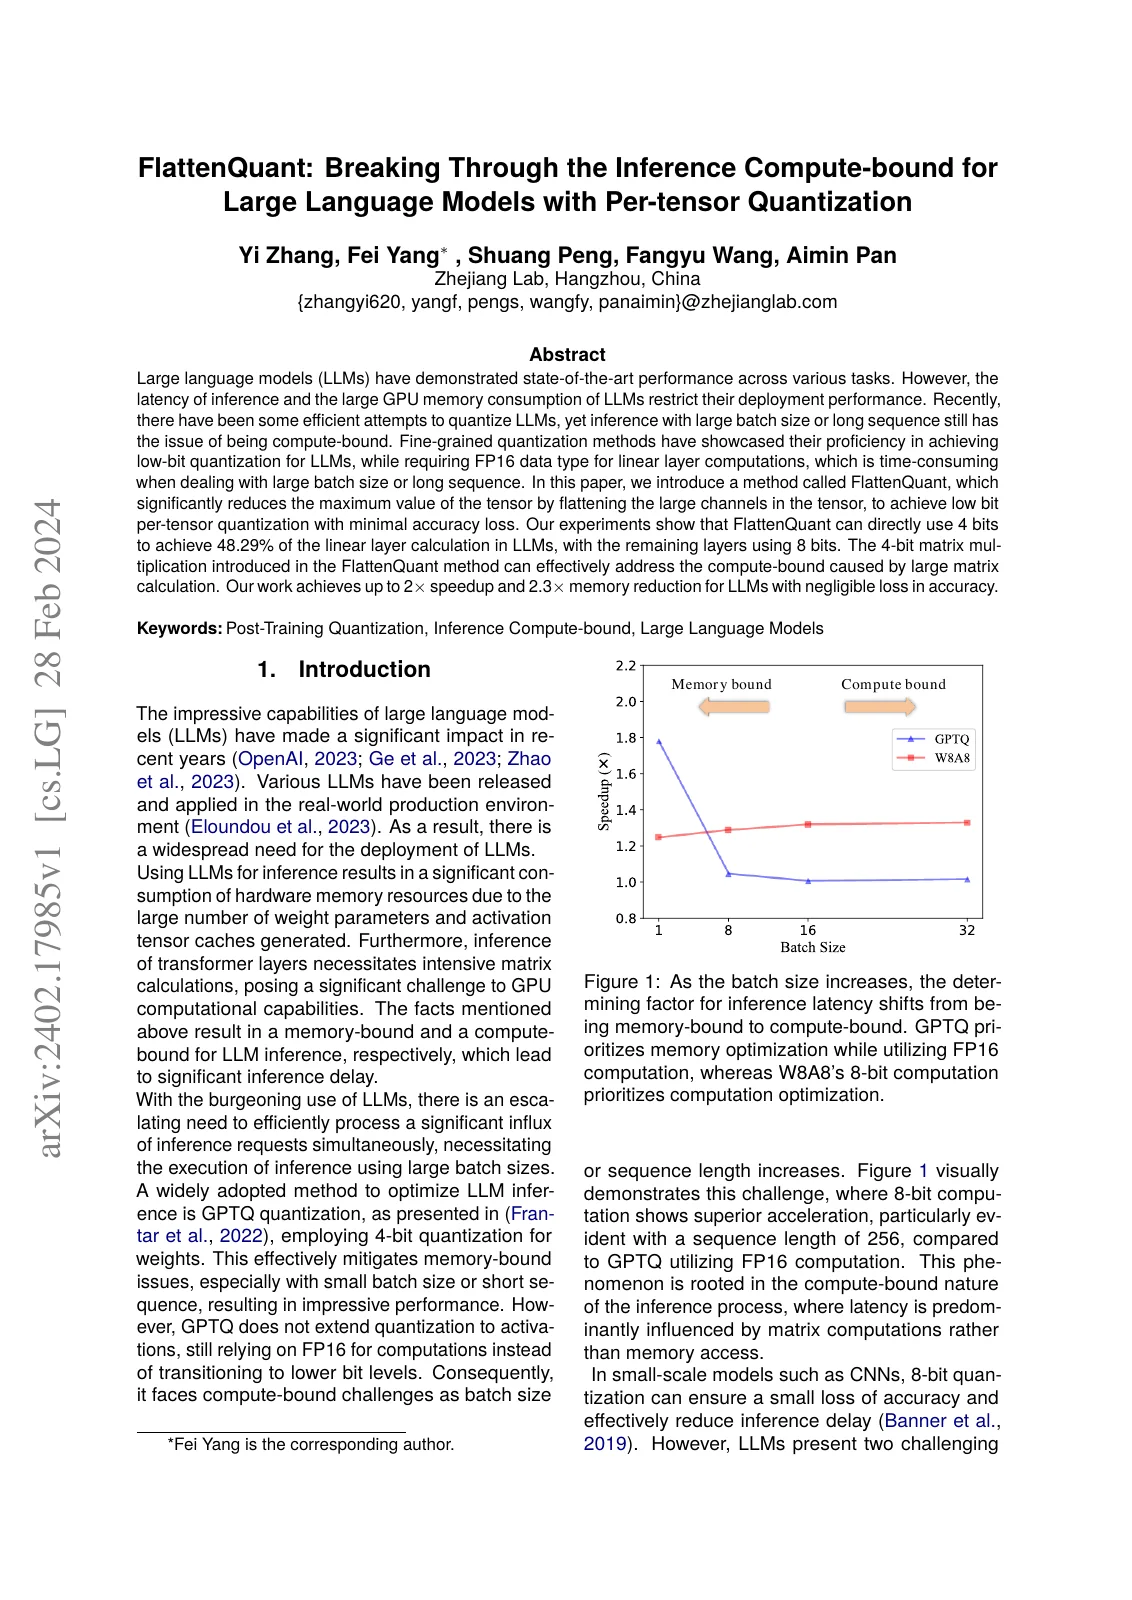
FlattenQuant: Breaking Through the Inference Compute-bound for Large Language Models with Per-tensor Quantization
In this reference
A quantization method designed to improve language-model inference efficiency.
Cite the original work
Yi Zhang & Fei Yang & Shuang Peng & Fangyu Wang & Aimin Pan (28 February 2024). FlattenQuant: Breaking Through the Inference Compute-bound for Large Language Models with Per-tensor Quantization [Research paper]. arXiv. https://arxiv.org/abs/2402.17985v1
View BibTeX
@misc{flattenquant_breaking_through_the_inference_compute_bound_for_large_language_models_w,
  author = {Yi Zhang and Fei Yang and Shuang Peng and Fangyu Wang and Aimin Pan},
  title = {{FlattenQuant: Breaking Through the Inference Compute-bound for Large Language Models with Per-tensor Quantization}},
  howpublished = {arXiv},
  url = {https://arxiv.org/abs/2402.17985v1},
  year = {2024}
}