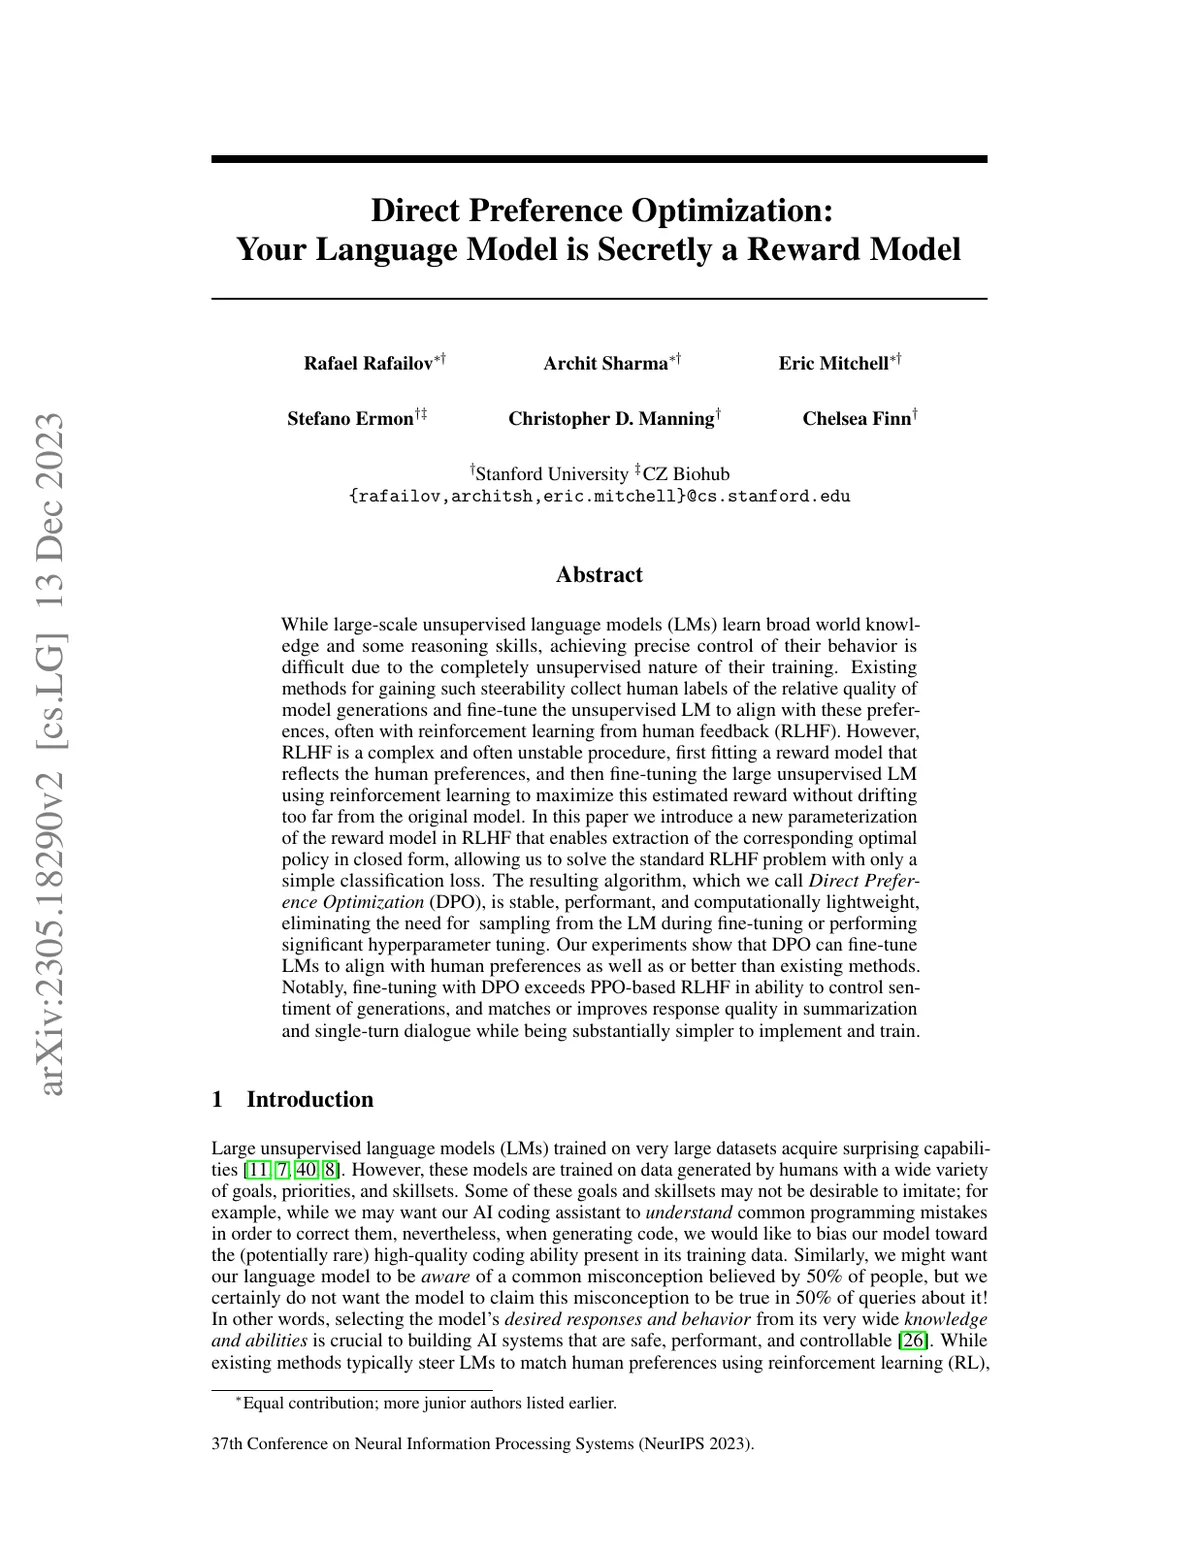
Direct Preference Optimization: Your Language Model is Secretly a Reward Model
In this reference
A method for learning from preferences without a separate reinforcement-learning reward model.
Cite the original work
Rafael Rafailov & Archit Sharma & Eric Mitchell & Stefano Ermon & Christopher D. Manning & Chelsea Finn (29 May 2023). Direct Preference Optimization: Your Language Model is Secretly a Reward Model [Research paper]. arXiv. https://arxiv.org/abs/2305.18290v2
View BibTeX
@misc{direct_preference_optimization_your_language_model_is_secretly_a_reward_model,
  author = {Rafael Rafailov and Archit Sharma and Eric Mitchell and Stefano Ermon and Christopher D. Manning and Chelsea Finn},
  title = {{Direct Preference Optimization: Your Language Model is Secretly a Reward Model}},
  howpublished = {arXiv},
  url = {https://arxiv.org/abs/2305.18290v2},
  year = {2023}
}